Legibility
When a dashboard cannot record a kind of work, decisions based on it will usually treat that work as if it does not exist.
Systems turn messy reality into categories they can compare and control, then risk hurting people and work that those categories leave out.
The dashboard made a useful engineer look unproductive
An engineering organisation wants more consistent performance decisions. It creates a dashboard that counts deployments, completed tickets and estimated points.
One engineer appears near the bottom because she ships fewer visible features, reviews risky changes, helps several teams debug shared infrastructure and prevents incidents before they reach the alerting system. The dashboard barely records that work. Prevention creates no incident ticket, mentoring lifts somebody else's output and an architectural mistake avoided in time can look like nothing happened.
Leadership treats the score as a complete account and removes her from the team.
Over the next quarter, reviews slow down, recurring failures return and several engineers carry work she had been doing for them. The dashboard measured the units it was designed to count. The organisation treated those units as everything valuable.
This is the legibility problem: large organisations turn messy reality into categories they can count and compare. People become roles, land becomes parcels, work becomes tickets, risk becomes a score and health becomes measurements.
Those categories make coordination possible. They also make it easy for promotion and staffing decisions to ignore work they cannot record.
How the dashboard changes the work
Making something legible usually follows four moves.
- Standardise. Turn varied local situations into shared categories.
- Compare. Rank, group or govern those categories from a distance.
- Allocate. Hand out money, authority, attention or punishment according to the record.
- Reshape. People and environments adapt to what the record rewards.
A performance dashboard does more than describe work. Once promotions and staffing depend on it, teams choose work that creates recognised units, mentoring falls away, preventive maintenance gets delayed and large tasks get split into countable pieces. Managers then have less evidence to justify work the dashboard cannot record.
Why shared categories are still useful
A large company cannot coordinate through personal familiarity alone. Shared roles, addresses, schemas and diagnostic categories make consistent decisions possible. The useful question is which details can be left out without changing the decision or hurting the people the category hides.
Every dashboard should be clear about what it can answer, what it leaves out and which decisions still need direct evidence from the work.
Repairing the performance decision
The organisation can keep the measurement. It needs to limit what that measurement gets to decide.
It could:
- Use the dashboard to identify questions rather than automatically rank people.
- Include reliability, review work and knowledge sharing without pretending every contribution fits one unit.
- Ask peers and teams that depend on the work where hidden support is concentrated.
- Look at prevented failures and difficult decisions as well as completed objects.
- Give the person affected a route to add missing context.
- Watch how people change their behaviour once the measurement affects them.
The dashboard can still reveal patterns. It should not make the final decision by itself.
The engineer's work becomes visible through several independent signals. The extra evidence also shows which reviews, maintenance and support work the original dashboard missed.
The mechanism across fields
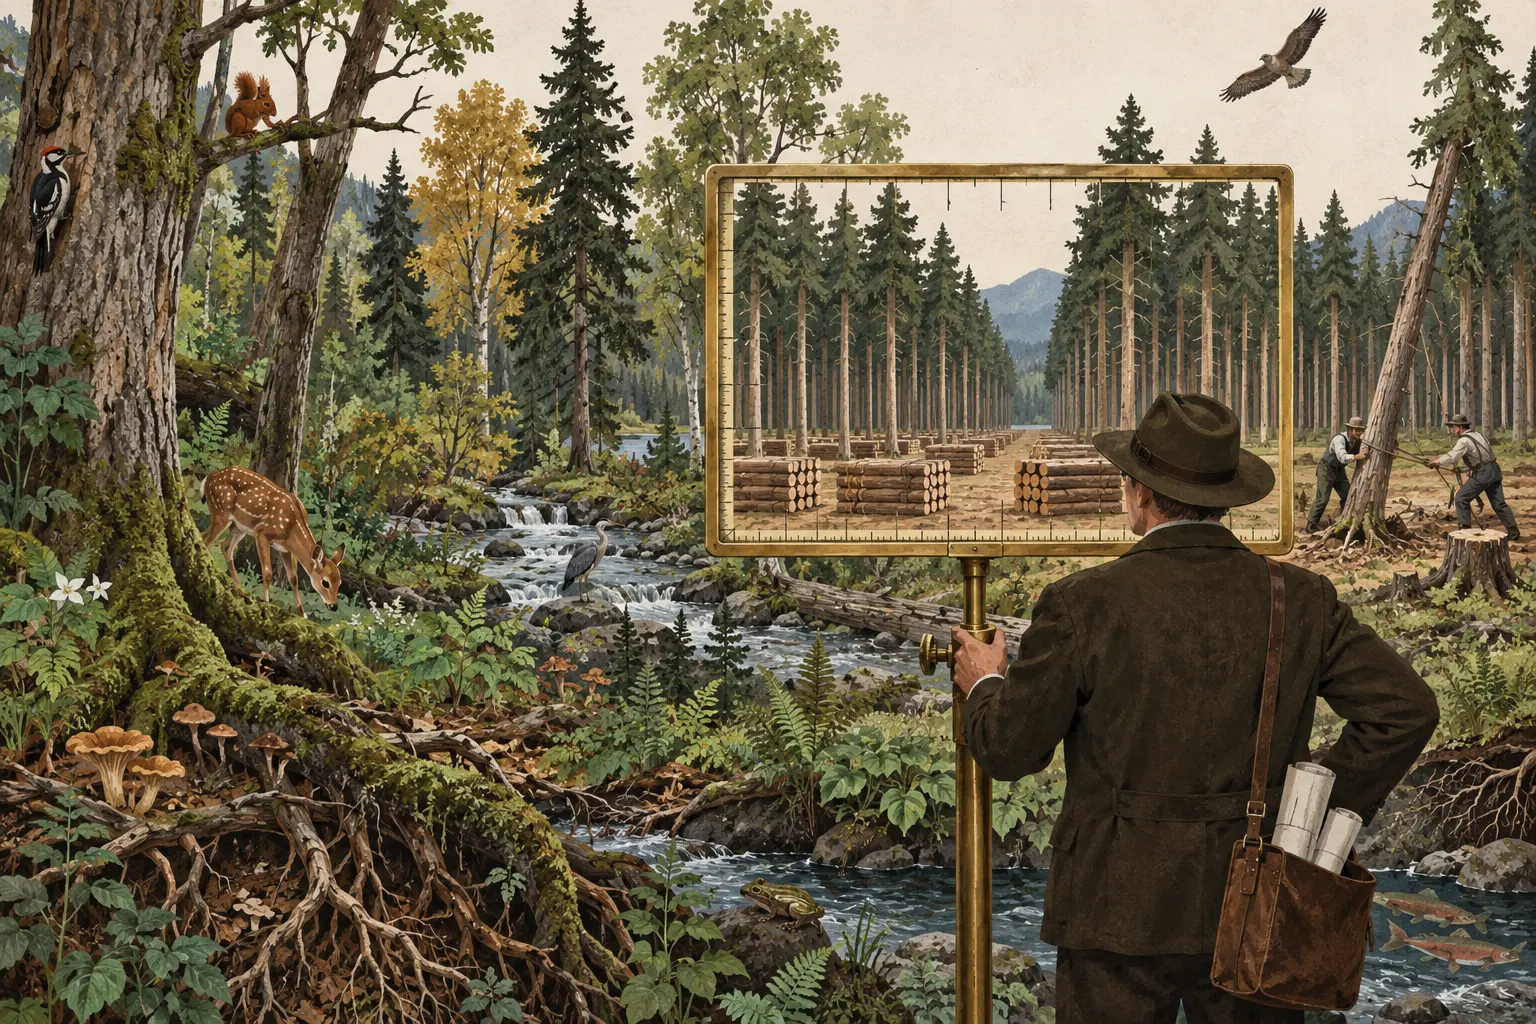
History, government and ecology. States made land easier to manage through official property maps, standard names, addresses and measured plots. That supported taxation, ownership records and public services. Scientific forestry did something similar by counting commercially useful timber and treating diverse forests as uniform stands. It could remove understory, mixed ages, soil relationships and local uses that kept the forest working. A property record or address can also protect someone from arbitrary decisions when the category fits their situation.
Software and data design. A schema turns messy reality into fields, types and allowed states. That makes searching, validation and automation possible. Facts that do not fit may go into an “other” bucket, become misleading defaults or get rejected entirely. Later software can then act as though the schema's inability to express something means it does not exist. Keep the original information and where it came from, so a later schema can use details the current fields cannot hold.
Organisational design, product and law. Metrics, forms, eligibility rules and risk bands let distant decision-makers treat many cases consistently. They also favour needs that fit the authorised categories. A customer with an unusual problem repeats the same explanation to several agents because the workflow has nowhere to keep the real situation. An appeal lets that customer add context the form could not hold and ask for the decision to be reviewed.
Whoever defines the categories also gets more control over which work and which people count.
Questions to ask before a dashboard or rule starts making decisions
Use this model when creating dashboards, schemas, organisational levels, compliance rules, scoring systems or standard workflows.
Ask:
- What must become comparable for this system to work?
- Which local distinctions will the categories erase?
- Who defines the categories?
- Who benefits from becoming easier to see?
- Who becomes an exception, an “other” or missing data?
- Which decisions may the representation make directly?
- Where can excluded context re-enter?
- How will we detect that people are reshaping behaviour to fit the model?
The more serious the decision, the more evidence it should require beyond one score or category.
Where standard categories help
It is easy to romanticise knowledge that a formal system cannot see.
Informal systems can hide favouritism, unsafe practice and unaccountable gatekeepers. A manager claiming that someone's value is “too nuanced to measure” may be protecting genuinely important work or avoiding evidence. Standard categories sometimes give overlooked people rights and consistency they couldn't obtain through discretion.
No system can preserve every detail. Refusing all simplification prevents coordination and makes decisions depend on whoever has proximity or influence.
Use simple measures to spot patterns, then require fuller evidence and a route to appeal before those measures decide something important about a person.
Nearby models
Map Is Not the Territory says every representation differs from reality. Legibility adds an institutional mechanism: the representation is used to allocate resources and exercise control, so the territory begins changing to fit the map.
Boundary Critique asks whose interests, knowledge and consequences were included in the system's definition. Legibility asks how the included reality was compressed into administratively usable categories and what that compression makes difficult to see.
Before deciding work has no value, check whether the categories simply fail to record what it prevents or makes possible.