Graceful Degradation
Before something fails, decide what must keep working and what can wait.
A system degrades gracefully when it turns off lower-priority work on purpose while keeping people safe, preserving the truth of its state and protecting the service they need most.
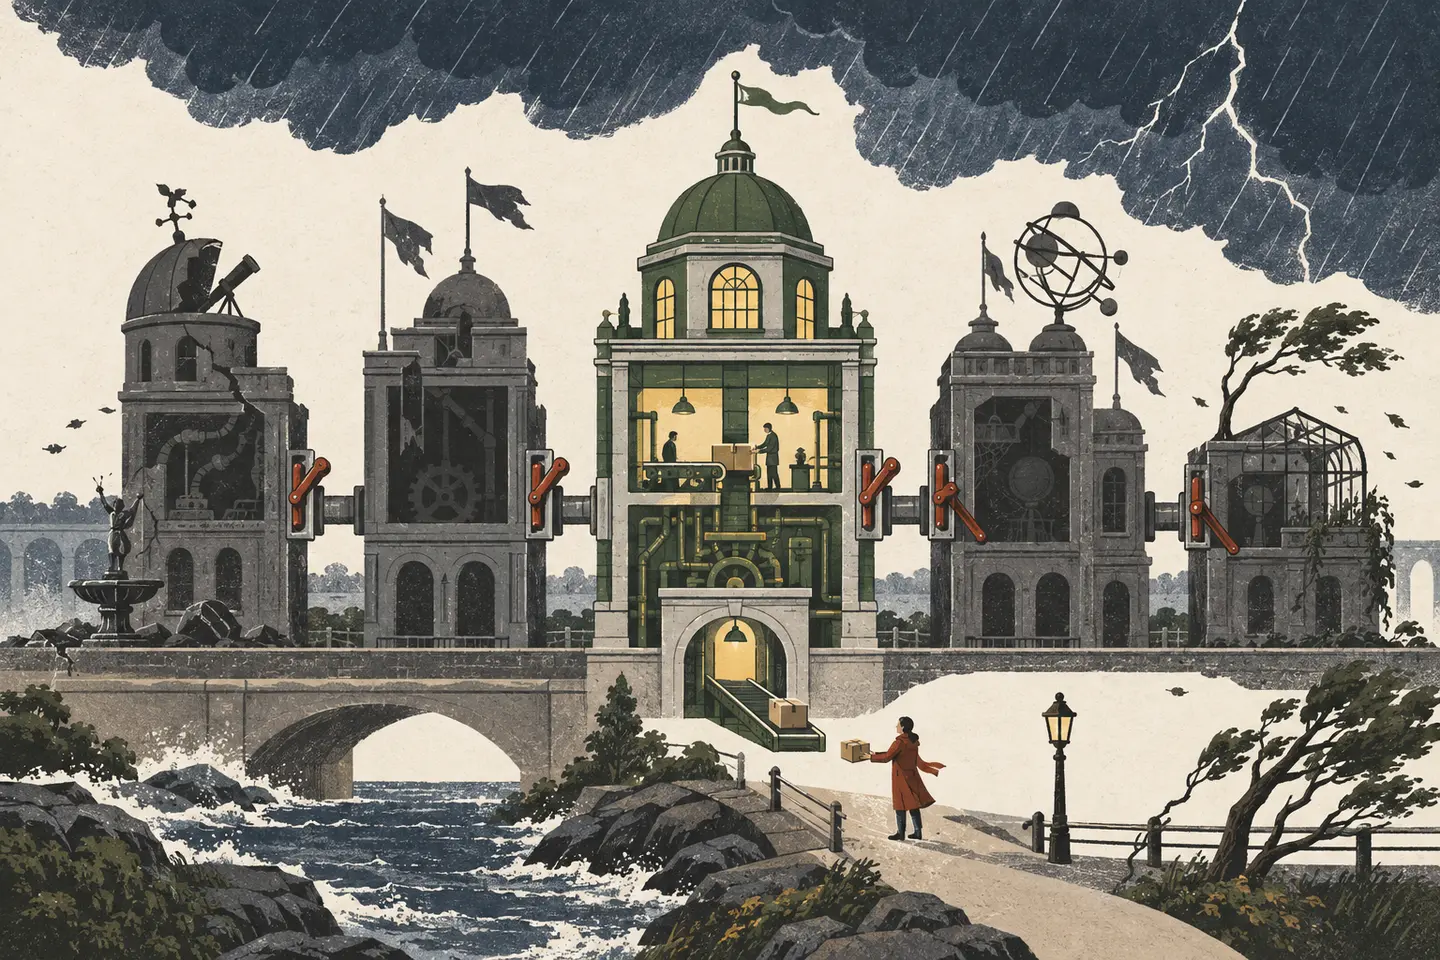
The provider stopped, then everything else followed
A payment product depends on an external provider for live rates and international transfers.
The provider slows down. Each request waits for a response, clients retry, worker threads fill and database connections remain occupied for longer. Soon customers can't load balances or transaction history, even though those functions don't need the failing provider.
Support sees the same blank state as the customer, so one person who is waiting for money keeps retrying. The retries add more load, and support has to investigate each case because the product can't show whether the transfer was accepted.
One transfer path failed. The system let that failure take down everything else.
Graceful Degradation means deliberately doing less during a failure or overload, so the system keeps people safe, tells the truth about what happened and preserves its most important useful service.
Decide what can become smaller
The payment system needs a clear priority order for which functions to disable first.
When the provider becomes too slow or fails too often, the system can stop sending new requests for a while, before the failing path uses the capacity needed by everything else. The product can temporarily disable new international quotes and transfers while preserving:
- Sign-in and account security
- Balances and transaction history
- Status for transfers already accepted
- Reconciliation and repair work
- A clear explanation of what is unavailable
- The evidence support needs to help a customer
If internal capacity continues falling, the system might serve a clearly marked read-only snapshot rather than accept new writes it can't safely complete. If identity or ledger integrity becomes uncertain, it should stop rather than improvise.
Choose the states before an incident:
- Full service: every normal capability is available.
- Reduced service: optional or expensive work is shed while the core promise remains useful.
- Safe stop: the system refuses work when continuing could corrupt state, violate rights or create irreversible harm.
Treat reduced service as an operating mode with defined triggers, permissions, customer states and a test for returning to full service.
When everything is called critical, overload gets to decide what fails, without caring what people need most.
What a degraded mode needs to preserve
A graceful design usually protects five things.
Priority. The system knows which user outcomes matter most. This has to be more precise than “payments are critical.” Seeing whether money moved may be more urgent than starting another transfer.
Isolation. A slow provider, expensive request or overloaded customer cannot be allowed to occupy every available connection and block unrelated work. Limit how much capacity each one can consume, and stop sending new requests to the slow provider when its share is full.
State integrity. Reduced service must not pretend to know more than it does. A transfer can say pending or unknown. The interface cannot call it complete just to look healthy.
Legibility. Customers and operators can tell which mode the system is in, what remains available and what happens next. Silent degradation creates duplicate actions, more support work and lost trust.
Recovery. The path back to full service is defined and tested. Queued work is replayed safely, stale views are refreshed and temporary restrictions are removed only after the underlying invariant holds again.
The best fallback is often smaller than the team first imagines. Every fallback adds code to maintain, state to reconcile and recovery work to test.
How this works in other fields
Software and distributed systems. Google describes ways to protect important work during overload: return simpler answers, slow down callers and reject lower-priority requests first. Google SRE's chapter on handling overload. The point is to drop less important work before it consumes the capacity needed for what matters most. A slightly old search result may be acceptable; stale information about money movement or access control may not be.
Power systems. When generation and demand fall out of balance, automatic underfrequency load shedding disconnects some demand to arrest declining frequency and preserve the wider grid. NERC describes it as a last-resort system-preservation measure. NERC's underfrequency load-shedding standard. A local interruption is painful, but an uncontrolled cascade can leave everyone without power and make recovery much harder. Deciding whose electricity is interrupted involves public duties that a technical controller can't settle alone.
Emergency medicine and organisational triage. When demand exceeds available attention, triage sorts work by urgency instead of processing it in arrival order. The WHO's integrated triage tool separates immediate, soon and waiting categories so scarce clinical capacity reaches time-critical cases first. WHO triage guidance. The same idea helps an organisation preserve incident response, payroll or customer recovery while delaying reports and routine projects. People's cases also require fairness, appeal and qualified judgment because a classification can affect someone's health, income or rights.
In each case, decide what must continue, what can wait and when the system must stop completely.
Define the degradation ladder
Use this model when:
- A service depends on external providers.
- Overload can spread through retries or shared resource pools.
- Some operations are more reversible or urgent than others.
- A full outage would hide information needed for recovery.
- Manual fallback exists but has limited capacity.
- People will keep acting when the system becomes ambiguous.
For each operating mode, define:
- Core promise: What useful outcome must remain available?
- Safety invariant: What must remain true even if nothing else works?
- Work to shed: Which features, users or tasks can wait?
- Trigger: Which measurable condition enters this mode?
- Isolation boundary: What prevents the failing part from consuming the rest?
- Customer state: What does the affected person see and what can they safely do?
- Operator authority: Who can enter, deepen or leave the mode?
- Recovery test: Which evidence proves full service is safe again?
Test the ladder by removing dependencies deliberately. Test the fallback with realistic state before relying on it during an incident.
When reduced service becomes the new normal
A degraded mode can hide chronic underinvestment. Teams may run in reduced service for months, normalise the loss and call it resilience. Temporary queues acquire permanent owners, manual work exhausts operators and customers with less power receive the worst version of the product.
Fallbacks also increase complexity. They can drift, expose stale data or fail precisely because they are rarely exercised. A graceful-degradation plan needs drills, expiry conditions and an owner for returning to normal.
Some systems shouldn't continue in a weaker mode. If identity can't be verified, a medical device can't measure safely or a financial ledger may be corrupt, the correct degraded behaviour may be a clear stop. When limited service would be unsafe, stop clearly, preserve the state needed for recovery and tell people what happened.
Related models
Fault Tolerance tries to preserve full functionality despite component failures, usually through redundancy, replication or failover. Graceful Degradation accepts that full function may no longer be possible and deliberately preserves a smaller useful service. Fault tolerance delays the need to degrade; it doesn't remove that need.
Fail-Safe Design moves a system towards a state that avoids unacceptable harm when something fails. That state may be a complete stop. Graceful Degradation continues limited service only where limited service remains safe, honest and useful.
Before failure, define which functions remain available, which ones stop and what evidence allows full service to resume.