End-to-End Principle
Put the final check where success can actually be known.
Put the final check with the person or system that can see whether the promised result really happened.
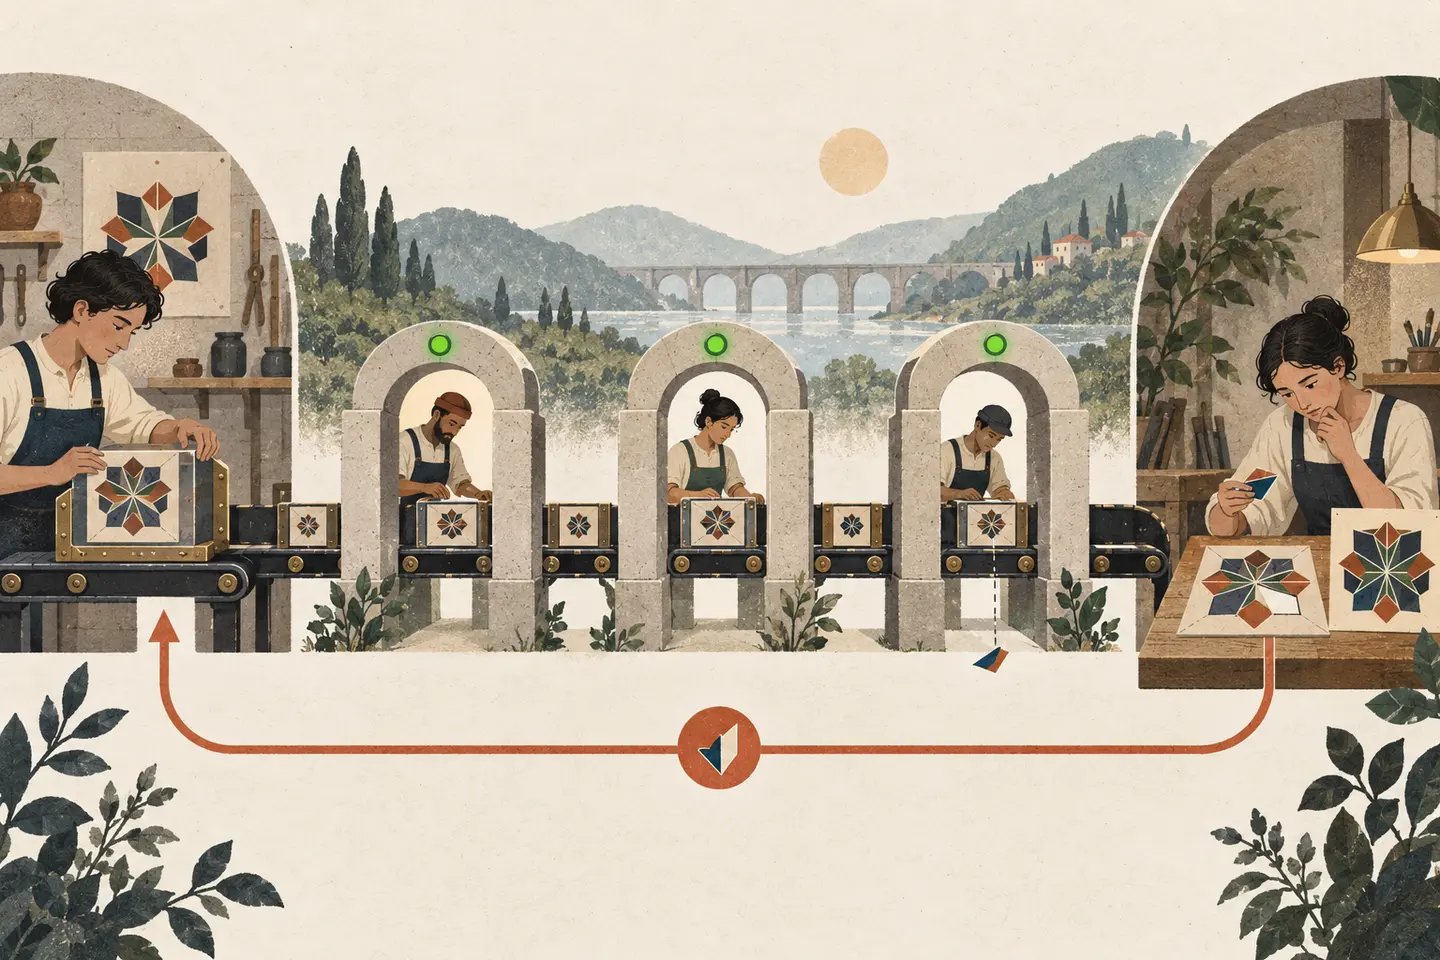
Every service says success and the recipient is still unpaid
A cross-border payout moves through several components:
- The app accepts the request.
- A risk check approves it.
- The system sets the sender's money aside.
- A payment provider accepts the instruction.
- A local partner forwards it to the recipient's bank.
- The app says the payment is complete.
Every component records success.
The recipient still has no money.
The final bank may accept the instruction before adding the money, reject it later or reverse it while records are being compared. The earlier participants cannot see the recipient's balance, yet the app treats each successful handoff as proof that the payout is complete.
Support sees the same green states and repeats them to a customer who is still waiting for rent money. Nobody investigates the mismatch until the customer complains.
The system has treated acceptance by the next participant as proof that the intended outcome occurred.
Put the final check where the information exists
The End-to-End Principle helps decide where a system should make its final guarantee.
In their influential paper “End-to-End Arguments in System Design”, Jerome Saltzer, David Reed and David Clark argued that some promises can be checked completely only by the applications at the two ends, because those applications know what was meant to happen.
Think of sending a file. Each network link can compare a small fingerprint, called a checksum, before passing a piece onward. The full file can still change while it is read, held in memory or saved, so the receiving app must compare the finished file with what the sender meant to send.
Checks inside the network still matter. They catch damage early and avoid repeating the entire transfer. They cannot replace the receiving app's final comparison with what the sender meant to send.
For the payout, a provider saying “accepted” is useful evidence, but it is not the final guarantee. The app must compare the money taken from the sender with reliable evidence that the recipient was credited, then resend, use another route, return the money or ask a person to investigate when they disagree.
This changes the meaning of a status:
- Submitted: the request entered the system.
- Accepted: the next participant took responsibility for processing it.
- Sent: an intermediate participant claims it moved onward.
- Settled: reliable evidence indicates the recipient was credited.
- Reconciled: the records of the sender's debit, the external transfer and the recipient's credit agree.
Each state can be useful without being presented as the next one.
How this works outside networks
Software. A messaging service saying “accepted” proves only that it stored a request. The app still has to check that the requested action happened once, so one order or charge is not accidentally created twice.
Law and contracts. A signed contract, cleared payment or submitted filing is an intermediate event. Performance is complete only when the promised good, right or remedy has reached the state the agreement defines. Acceptance tests, warranties, receipts and appeal rights place verification with parties or institutions that can judge the relevant outcome. The analogy has a limit: legal success is often contested rather than mechanically observable, so authority and procedure matter alongside information.
Organisations, logistics and product design. A parcel scan proves that a depot handled an item; proof of delivery addresses whether the intended recipient received it. Inside a company, five teams can meet their internal response targets while the customer journey fails between them. Give one owner responsibility for checking whether the customer received the promised result and repairing cases where every team met its local target but the journey still failed.
In each case, an intermediate participant can confirm its own handoff, while the final check must sit with whoever can see whether the intended result happened.
Where should the final check sit?
Use the End-to-End Principle when work crosses several services, providers, teams or institutions and each participant can succeed locally while the overall outcome fails.
Ask:
- What exact result does the user believe was promised?
- Which participant can directly observe that result?
- Which current statuses say only that someone accepted the work or intends to continue it?
- Which reliable source distinguishes completion from progress?
- When should the system stop waiting and begin repair?
- Who can retry, compensate, reverse or escalate?
- Which lower-level checks cheaply prevent common failures?
- What evidence should remain available for disputes and debugging?
The payout can keep every intermediate acknowledgement while delaying “completed” until evidence arrives that the recipient was credited. If that evidence does not arrive by a deadline, mark the payment uncertain. One owner then compares the records and repairs any mismatch before the customer has to complain.
Where this can go wrong
Waiting for final verification may be slow, and making the app repeat every network check can waste work. If one small piece of data is damaged, it is cheaper for nearby network equipment to resend that piece than to repeat the entire journey. Fraud, safety and privacy checks may also need to happen earlier because waiting until the end could allow unacceptable harm.
The people or systems at the ends may be dishonest, unavailable or unable to see the result directly. The final check may then need proof from an independent party, a record everyone shares or an agreed person who can resolve disputes.
The principle therefore doesn't remove intermediate responsibility. It separates two purposes:
- Earlier checks improve speed, contain common failures and catch problems sooner.
- The person or system that can see the full promised result must own the final claim that it happened.
Related models
Error Correction asks how a system can detect damage, contain it and restore a valid result. The End-to-End Principle asks where the final check and promise to repair must live. A network can correct local errors while the receiving app still verifies the complete result.
Defence in Depth uses several protections so one failure cannot defeat the whole system. End-to-end reasoning asks which participant can see enough to make the final claim. Several green checks can still leave that claim unverified.
A successful handoff doesn't prove that the user received the required result. Keep local checks for speed and containment, then verify the full result where it can actually be observed.