Double-Loop Learning
Fix the immediate problem, then check whether the rule behind it keeps creating the same problem.
Use feedback to fix the action, then change the rule behind it when that rule keeps creating the same failure.
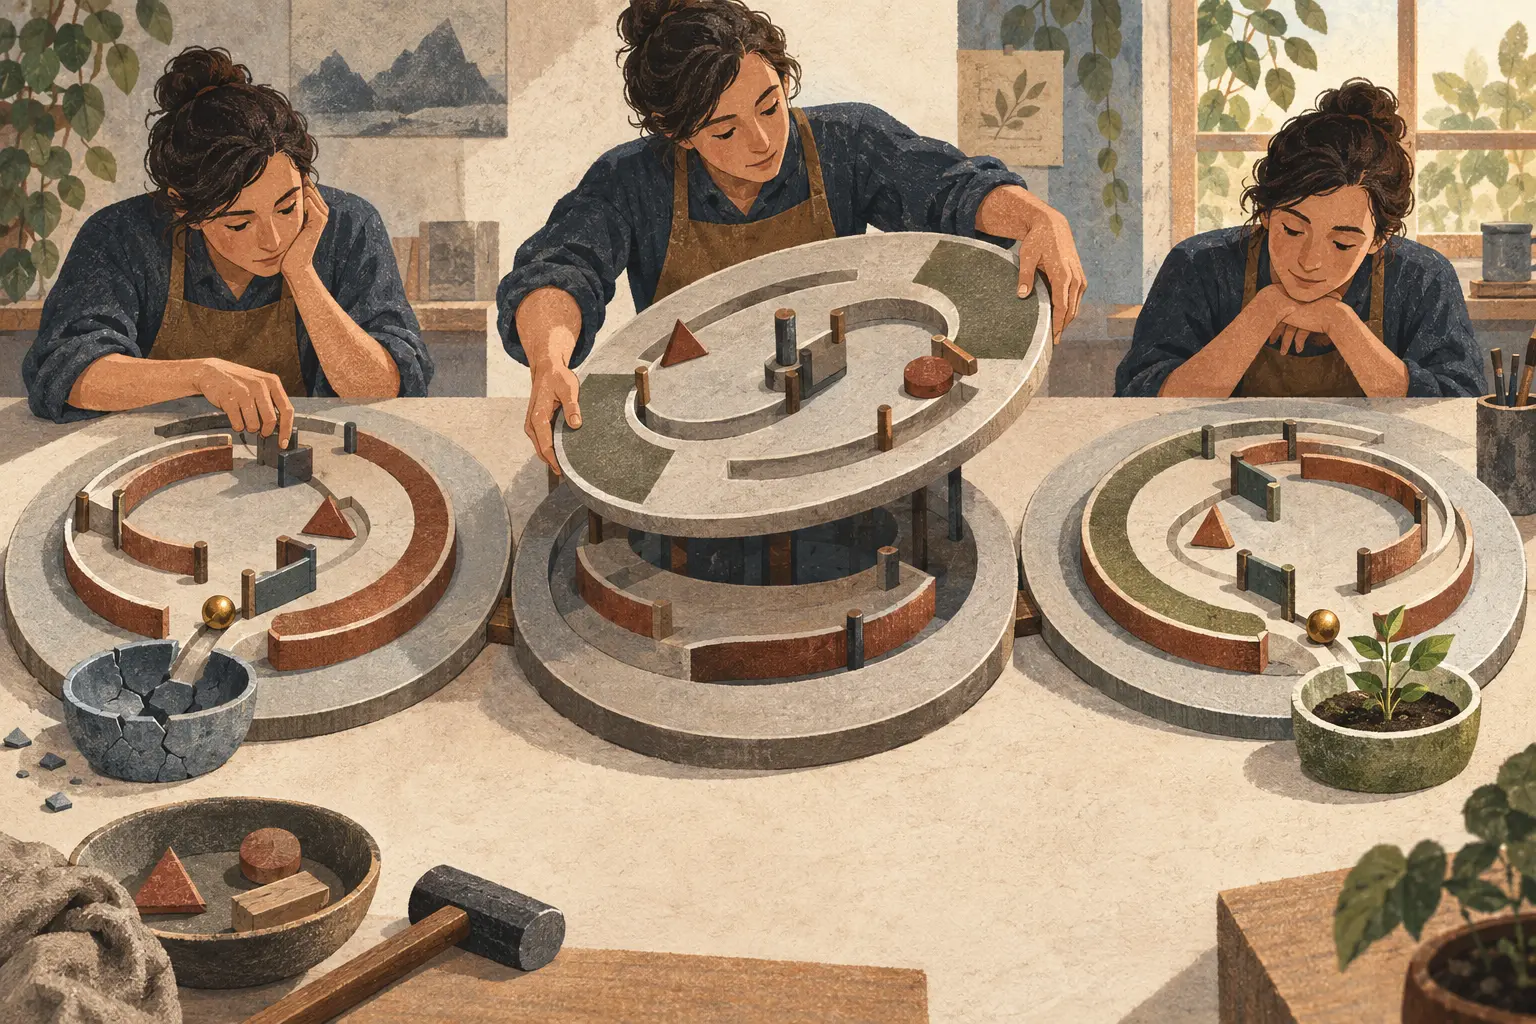
Fixing the queue, then fixing why it exists
A support team keeps missing its response-time target.
The first repair is sensible: the team sorts messages more carefully, drafts replies for common problems, adds another person to cover the busiest period and writes shorter notes. The queue shrinks for several weeks.
Then two product launches create problems customers have not faced before, and the queue returns. One analyst who understands the old workflows has to resolve most of them, even though the launch plan never made time for that work.
The organisation improved how it followed the existing rule:
Product teams call the feature launched. Support handles the unusual cases afterwards.
That's single-loop learning. Feedback reveals a gap, so the action changes while the goal, assumption or rule behind it stays fixed.
The second repair begins with a more uncomfortable question:
Why is handling these cases defined as Support's problem after the product has already been called launched?
Now the organisation changes the launch rule. A product isn't finished until likely failure cases have been tested, the person responsible for recovery is named, and Support has time for the extra work. The product owner stays involved during the first week. The team measures whether the feature keeps working when things go wrong, rather than treating release as completion.
Double-Loop Learning means using feedback to fix the action and, when the evidence calls for it, changing the goal, assumption, or rule behind that action.
When the second loop is worth opening
The difference between the two loops is straightforward.
Single loop:
goal or rule → action → result → adjust action
Double loop:
goal or rule → action → result → inspect goal or rule → revise system
The second loop does not replace the first. A production incident still needs containment before an architecture debate. A missed payment still needs correction before the policy review.
Use the second loop when the same kind of error returns after several fixes.
At that point, improving the same response may leave the rule that keeps creating the problem untouched.
The rules that sit underneath the action
Chris Argyris called the values, goals, and assumptions behind an action governing variables. His 1977 account of Double-Loop Learning describes how organisations often fix the visible error while leaving those deeper rules untouched. Chris Argyris, “Double Loop Learning in Organizations”.
In practice, a governing variable might be:
- “A launch is successful once the feature is available.”
- “Senior approval reduces risk.”
- “More choice is always better for the customer.”
- “Keeping every service independent increases team autonomy.”
- “A fast response matters more than a complete explanation.”
- “The plan should not change after resources have been committed.”
You can usually see these rules in the metrics, budgets, stop authority and explanations a review accepts.
A useful double-loop review asks:
- What result did we intend?
- Which action failed to produce it?
- Which goal, assumption or rule made that action sensible?
- What evidence now challenges that governing variable?
- What replacement rule would produce different choices?
- How can we test the replacement without destabilising the whole system?
The review is useful only when it produces a different rule that changes what the team does next.
How this works in other fields
Control systems and software. A thermostat uses feedback to keep a room near a chosen temperature: it turns the heat up or down without questioning the target. A more adaptive system may change the target when the room is empty or energy is scarce. Software teams make the same move when they stop adjusting how many times a failed request is repeated and ask whether the two systems need to wait on each other at all. People still decide whose comfort, cost or safety deserves priority.
Science and mathematical modelling. Evidence can change a number inside a model or show that the model is missing part of reality. Changing an estimated failure rate corrects the existing model. Discovering that several failures share one cause may require a different model. Organisational rules are harder to test because judgment and power also shape them.
Organisational design and law. A manager can enforce an approval policy more consistently, or ask whether the approval step gives authority to the person with the relevant information. A court can correct the application of a rule in one case, while a legislature or constitutional review process may revise the rule itself. Institutions separate these loops because reopening foundational rules for every case would create instability, while never reopening them would preserve systematic harm.
In each case, review the underlying rule when following it correctly keeps reproducing the same error.
When to inspect the frame
Reach for Double-Loop Learning when:
- The same class of incident returns after several fixes.
- Performance improves locally while the wider outcome gets worse.
- Exceptions require growing amounts of hidden work.
- People can explain what failed but can't challenge why the goal is defined that way.
- A metric is achieved while trust, quality or resilience declines.
- Teams become better at recovery without reducing how often recovery is needed.
- New evidence fits none of the options the decision process permits.
Look especially for recurring phrases such as “people need more training,” “we need another approval” or “the team must communicate better.” Each may be true. Each can also protect a rule that deserves examination.
Where this can go wrong
A team can misuse this model by reopening its strategy whenever execution becomes difficult, treating ordinary variance or discomfort as evidence that the underlying assumptions are wrong. Constantly renegotiating goals destroys the stable expectations needed for coordination and sustained work.
Some boundaries shouldn't become optional because results are inconvenient. Rights, safety constraints and contractual duties aren't merely hypotheses to discard when they reduce short-term performance.
Sequence matters:
- Contain urgent harm.
- Correct the immediate action.
- Check whether the error is recurring or structurally generated.
- Reopen only the assumptions for which evidence has become meaningfully different.
- Test the replacement rule on a small, reversible part of the system.
The rules should be stable enough for people to coordinate and still change when the evidence against them becomes strong.
Related models
Root Cause Analysis traces the causal chain behind a particular failure. It may discover a broken dependency, missing control or ambiguous handoff while leaving the governing objective unchanged. Double-Loop Learning asks whether the objective, policy or assumption that defined the original action should itself change.
Bayesian Updating changes confidence in competing explanations as evidence arrives. It often compares explanations already on the list. Double-Loop Learning may change the list itself, the decision rule or the goal that determines what counts as useful evidence.
When the same correction keeps returning, review the goal or rule that keeps producing it.